At a glance
- Takes
- Any payload, plus the variables your conditions reference
- Emits
- records, first, count, columns, columnTypes, truncated
- Good for
- Reading back what an earlier flow stored
Set it up
Pick the database, type the table name, and add conditions. A query against a table nobody has written to yet reports zero records instead of failing, so a flow that queries before it ever inserts survives its own first run.
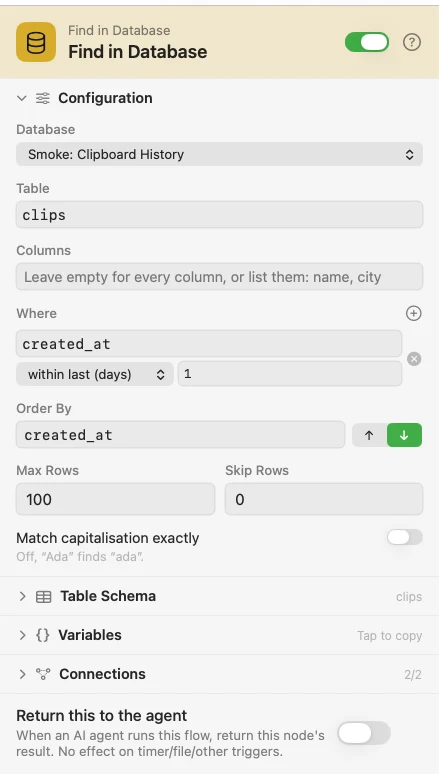
Configure
| Field | Default | What it does |
|---|---|---|
| Database | — | Which database to read. The picker fills in the id; the node finds its database by that id, never by name. |
| Table | — | The table to read. |
| Columns | every column | Leave empty for all, or list them: name, city. A name that isn't in the table is an error. |
| Where | — | Conditions, each a column, an operator, and usually a value. Empty matches every row. |
| Match | All of the conditions | All (AND) or Any (OR). |
| Order By | — | One column, optionally asc or desc — created_at desc is the usual "newest first". Anything richer belongs in Run SQL. |
| Max Rows | 100 | Ask for more than 5,000 and you get 5,000, with a line in the run log. |
| Skip Rows | 0 | How many matching rows to step over first. With Max Rows, this is how you page. |
| Match capitalisation exactly | Off | Off means equals, contains and friends ignore case. |
The where-builder offers eighteen operators: equals, does not equal, contains, does not contain, starts with, ends with, is greater than, is at least, is less than, is at most, older than (days), within last (days), is one of, is not one of, is null, is not null, is empty, is not empty.
Three behave more helpfully than raw SQL. equals compiles to SQL IS, so comparing against nothing finds the rows holding nothing. contains escapes % and _, so searching for 100% finds "100% done" rather than everything. is not one of keeps rows whose value is null, which plain NOT IN drops.
Output
Every key is available downstream as {{key}}.
| Key | Type | Value |
|---|---|---|
records | Array | The rows, as a real array of objects — loop over it, or index it: {{records.0.body}}. Empty array when nothing matched |
first | Object | The leading row, so a field can just say {{first.body}}. null on an empty result, never missing |
count | Number | How many records came back — the length of records, never what the table holds |
columns | Array | Column names in selection order. A name selected twice is suffixed _2, and that suffixed name is the key inside each record |
columnTypes | Array | text, integer, real, blob or null, one per column |
truncated | Boolean | true when the result hit the 5,000-row or 8 MB ceiling |
truncated_reason | String | row_limit or byte_limit; null when nothing was cut |
Example: read back today's clippings
Input runs the flow by hand. Find in Database reads clips with created_at within last (days) 1, newest first. For Each walks {{records}} and Log prints each one.
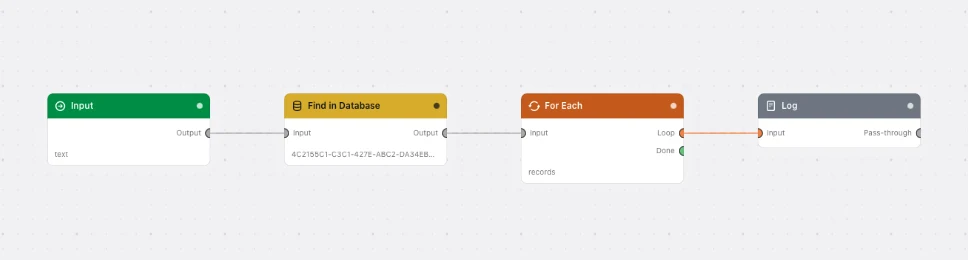
Paste this into the Flow Builder to get the same flow:
Read the clips table in Clipboard History for rows from the last day, newest first, then loop over the results and log each one.
Good to know
A condition that can't be worked out stops the run. A missing variable, a value like clip-{{n}} with no n upstream, or a rule left without a column — all three refuse rather than quietly dropping the condition, because a vanished condition changes which rows come back.
Numbers compare as numbers, even in a text column. Imported data is full of numbers stored as strings, and a text comparison ranks "10" below "9". A cell that is not a number at all — unknown, N/A — matches no numeric comparison in either direction.
SQLite has no boolean type. true is stored as 1 and reads back as the number 1, so match a flag with equals 1.
A flow that arrives from someone else needs a database picked. The id is per-machine, so an imported node is blanked and marked needs setup, keeping the author's name for it so you can see what it was.